- Keep retrieval quality, latency and cost under control across millions of documents
- Apply query expansion, cross-encoder re-ranking, metadata filtering and prompt compression
- Design RAG systems that survive failures in production
- Judge how far a well-engineered RAG system can go before you need an AI agent
Java developers and architects who have a RAG demo working and need it to run reliably at scale.
Your RAG prototype works. Now what?
The engineering challenge begins when the system needs to handle millions of documents, maintain retrieval quality, survive failures, control latency, manage cost, and operate reliably in production.
This session is a practical deep-dive into the engineering techniques that can take RAG beyond a prototype.
We will talk about - query expansion, - cross-encoder re-ranking, - metadata filtering, - prompt compression
And in a world increasingly focused on Agentic AI, we will take a step back and look at an equally important question: how far can we take a well-engineered RAG system before we actually need an AI agent?
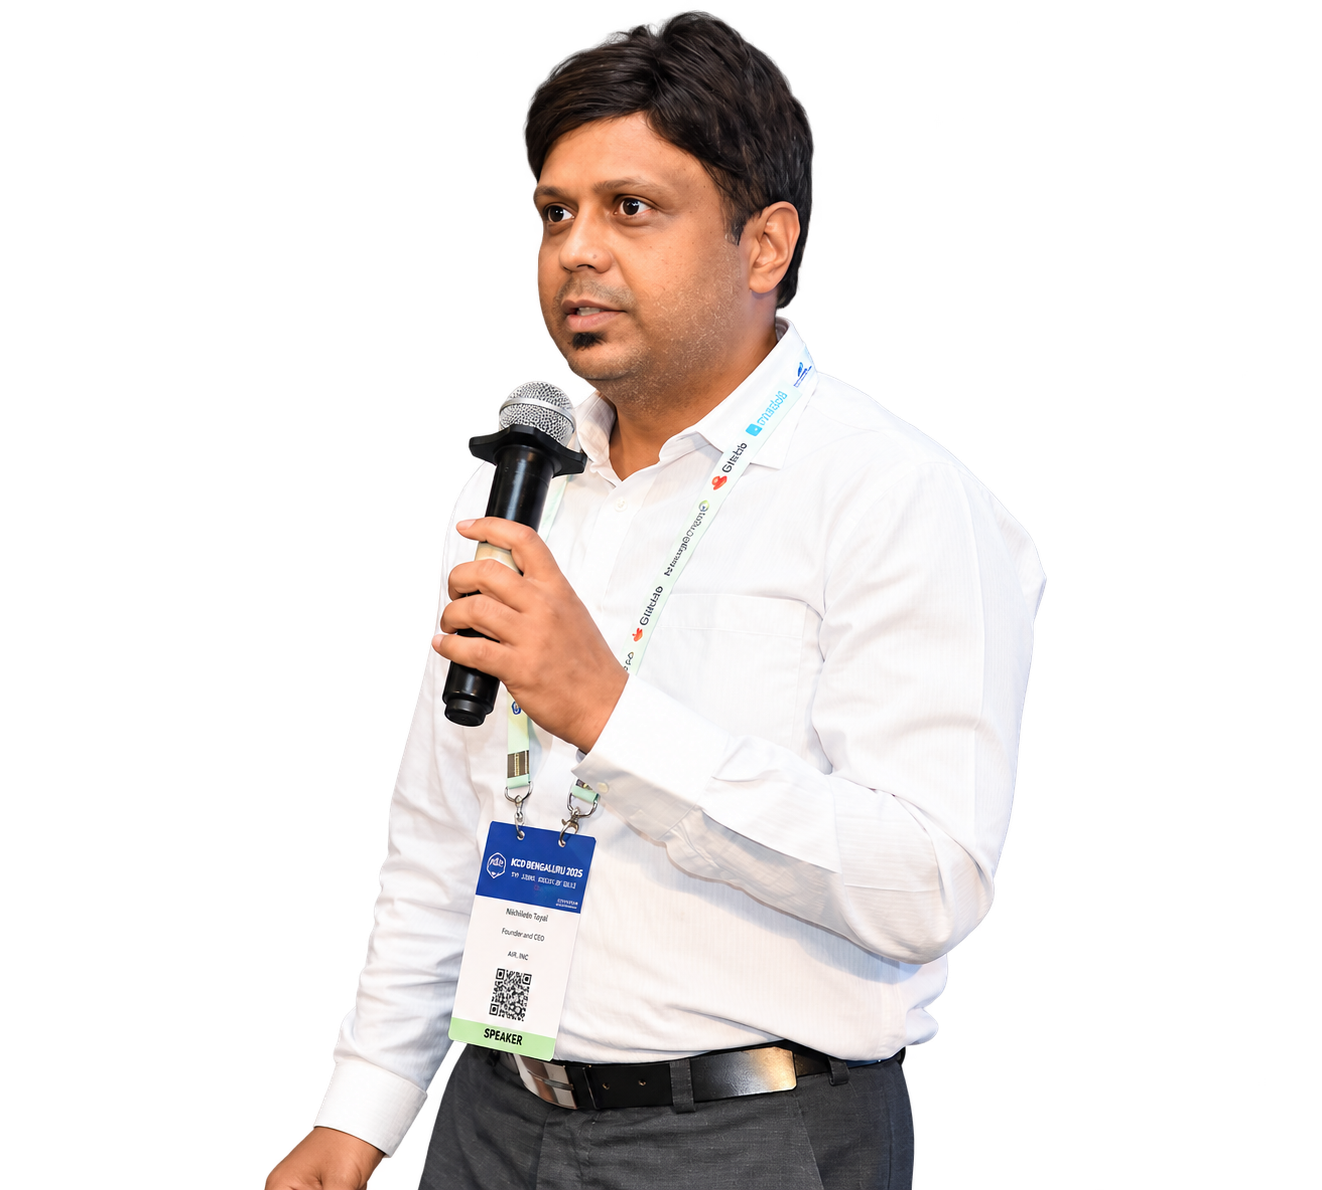
Nikhilesh Tayal
Founder & Teacher · AI ML
Nikhilesh is an entrepreneur, teacher, and tech nerd. He is an IIT Kharagpur alumnus and a Google Developer Expert in AI, with over 18,000 followers on LinkedIn.
Full profile →More to explore
Two days, one community. See the full agenda →
Take these sessions back to your team
Every pass includes the conference talks. Add the hands-on workshop on 17 Oct with the Regular + Workshop Pass or above.